gpt-image-2, gpt-image-2.5-flare, and gpt-image-2.5-sunburst to generate product images, advertising assets, or design drafts, developers often run into several frustrating questions:
- Why do calls with the same model and parameters produce different results at different times?
- Why does a request for 4K or a specific size sometimes return a downgraded 1K image?
- When you use
Maskfor local editing orquality=high, does it actually take effect? What standard is used to charge for the result?
200 OK is far from enough. The image must be generated, fit the target layout, and have transparent, predictable costs—all three conditions must be met at once.
To help developers understand the actual behavior of these 3 models, BetterToken has implemented capability-based intelligent routing, default-parameter normalization, pre-validation rejection of invalid parameters, and transparent billing based on the pixels actually delivered at the gateway layer. Based on the latest test data and price snapshot from 2026-10-19, this guide uses real generated images and billing records to show you how to make requests, what results to expect, and what objective limits the models still have.
Note: This guide focuses ongpt-image-2,gpt-image-2.5-flare, andgpt-image-2.5-sunburst. The Nano Banana model series has different parameters and billing, which we will cover separately to avoid confusion.
1. Why can the same model and parameters produce different results?
In practice, different service nodes behind the same model name often vary in their actual capabilities and stability. Some routes support only basic 1K image generation, while others can deliver high-resolution images at2048×2048 or even 3840×2160. Nodes also differ in their support for quality values, reference-image editing, and Mask masks.
If a platform simply forwards requests blindly based on the model name, developers will frequently encounter situations such as “requested 4K but received a small 1K image,” “sent a Mask and got an error,” or “had to keep adjusting parameters.” That is why we need a rigorous testing standard that checks “the API accepts the parameter” and “the actual delivered result” separately.
2. How did we test: what counts as “supported”?
To keep the conclusions objective and reliable, our regression tests for the production release covered 22 standard test scenarios (17 valid requests successfully delivered 18 images; 5 invalid-parameter scenarios were rejected as expected without billing). We also generated product images and Mask-editing samples for common ecommerce use cases. Our verification criteria are straightforward:- Decode the original file’s pixels: We do not rely on API declarations. For every delivered image, we decode the original file to read its width and height, then compare the billing tier in the response with the actual account deduction.
- Determine whether dimensions meet the target: We compare the actual width and height with each explicitly requested dimension. A larger returned dimension passes; if either dimension is more than 5% smaller than the target, the result fails (Note: this criterion is used to evaluate test results strictly. It does not mean the API automatically discards valid images that miss the requested dimensions.) If dimensions are omitted or set to
auto, we treat the request as having no fixed-canvas target. - Report parameter acceptance and actual results separately: An error-free response means only that “the parameter was accepted.” Whether
Maskachieves strict region isolation and whetherquality=highproduces a perceptible improvement must be judged from the final image.
3. What did the tests find: which parameters are easiest to misunderstand?
Comparing request parameters, delivered pixels, and final billing side by side revealed several key facts that developers are most likely to misunderstand:
The tests also showed the following behavior for parameter compatibility and error handling:
- Default-parameter tolerance: Image generation works whether
qualityandsizeare omitted, passed asnull, or explicitly set to"auto". - How to request 4K correctly: “4K” is a billing-tier concept; it does not mean that a
4096x4096square image is supported. To request a high-resolution image at the 4K level, use the landscape size3840x2160. - Invalid parameters rejected without billing: Requests with
4096x4096,stream=true, an emptyquality="", an emptysize="", orn=0all returnedHTTP 400errors and incurred no charge at all.
4. What does BetterToken provide: no need to adapt each route yourself
To handle complex size drift and differences between underlying nodes, BetterToken takes care of four things at the gateway layer, so you do not need to write separate adaptation code for every route:- Intelligent routing based on capabilities: The system automatically matches your model, target size (such as 2K/4K), and whether your request includes image-editing/
Maskparameters to an available service with the corresponding capabilities. - Unified API and parameter fallbacks: The standardized
POST /v1/images/generations(image generation) andPOST /v1/images/edits(reference-image/Mask editing) endpoints automatically handlenull,auto, and omitted parameters, and reject invalid input directly at the gateway layer. - Transparent reporting of actual dimensions and billing details: Along with the image data, the
bettertoken_image_billingfield in the response body tells you the image’s actual decoded width and height (width/height), billing tier (billing_resolution), currency, and settlement amount (settled_amount). - A clear distinction between two core concepts:
- Supporting the
Maskparameter ≠ pixel-precise inpainting: The API supports uploading a reference image and Mask for editing, but some test results also changed protected areas outside the mask. For example, in our geometric two-circle test, the left circle was transparent and requested to change color, while the right circle was opaque and meant to be protected; both circles changed color in the result. Therefore, we explicitly support passing the Mask parameter, but do not guarantee strict pixel-level region isolation every time. - Supporting the
qualityparameter ≠ guaranteeing a fixed degree of image-quality improvement: The API accepts parameters such as"auto"or"high"and routes them correctly. However, because every image generation is stochastic, we do not overstate based on a single sample thathighwill always improve quality by a particular percentage.
- Supporting the
⚠️ Two real limitations to understand before integration:
- Capability-based routing does not mean pixels are strictly fixed on every request: Due to differences in underlying service outputs, actual pixels can fluctuate even when routing reaches the appropriate node. For example, today’s samples still include a request for
1024x1024that returned1024×936, and a request for3840x2160that returned3840×2161. If your business is highly sensitive to canvas proportions, crop or post-process based on the actual dimensions returned.- A 1K request may not ultimately be billed at 1K: The billing system assigns a tier based on the specification of the valid image actually delivered. Today, the two 2.5 models (and
gpt-image-2in some cases) returned1254×1254images with more pixels when asked for1024x1024; the system classified these as 2K-tier images and billed them accordingly.
5. Support across the 3 models: which model should I call, and what value should I pass?
The capability configuration and test coverage forgpt-image-2, gpt-image-2.5-flare, and gpt-image-2.5-sunburst are as follows:
Note: “Delivered in this round of tests” in the table means that an image and billing sample were directly delivered in today’s regression tests and case generation. “Routing configuration aligned to support it” means the platform has aligned the configuration for the corresponding capability, but did not repeat requests for every combination in today’s regression tests.
6. Two real image examples: what do the results actually look like?
To show the actual generation quality, we followed the writing approach in the official OpenAI image prompting guide—“specific subject + material texture + light direction + composition and aspect ratio + exclusions”—and used the BetterToken API to generate the following two ecommerce examples (original outputs retained with no post-processing).Example A: Ecommerce product photography, showing 1K / 2K / 4K sizes and details
Scene design (Chinese concept):Generate a realistic ecommerce studio photograph: a coral-red ceramic mug (handle facing right) sits on a pale gray stone countertop, with a folded beige linen cloth to its left. The mug has the clear white text “BETTER DAY” printed on it. Soft side lighting from the upper left; retain subtle reflections on the ceramic glaze, linen fibers, and natural contact shadows. Keep the entire mug centered in frame, with a simple neutral background and no other objects, watermark, or extra text.Actual English prompt used:
gpt-image-2 (quality="high", 1 image per request) and kept the prompt above exactly the same. Instead of trying to get a higher resolution by putting “4K” in the prompt, we requested three size tiers using only the size parameter:
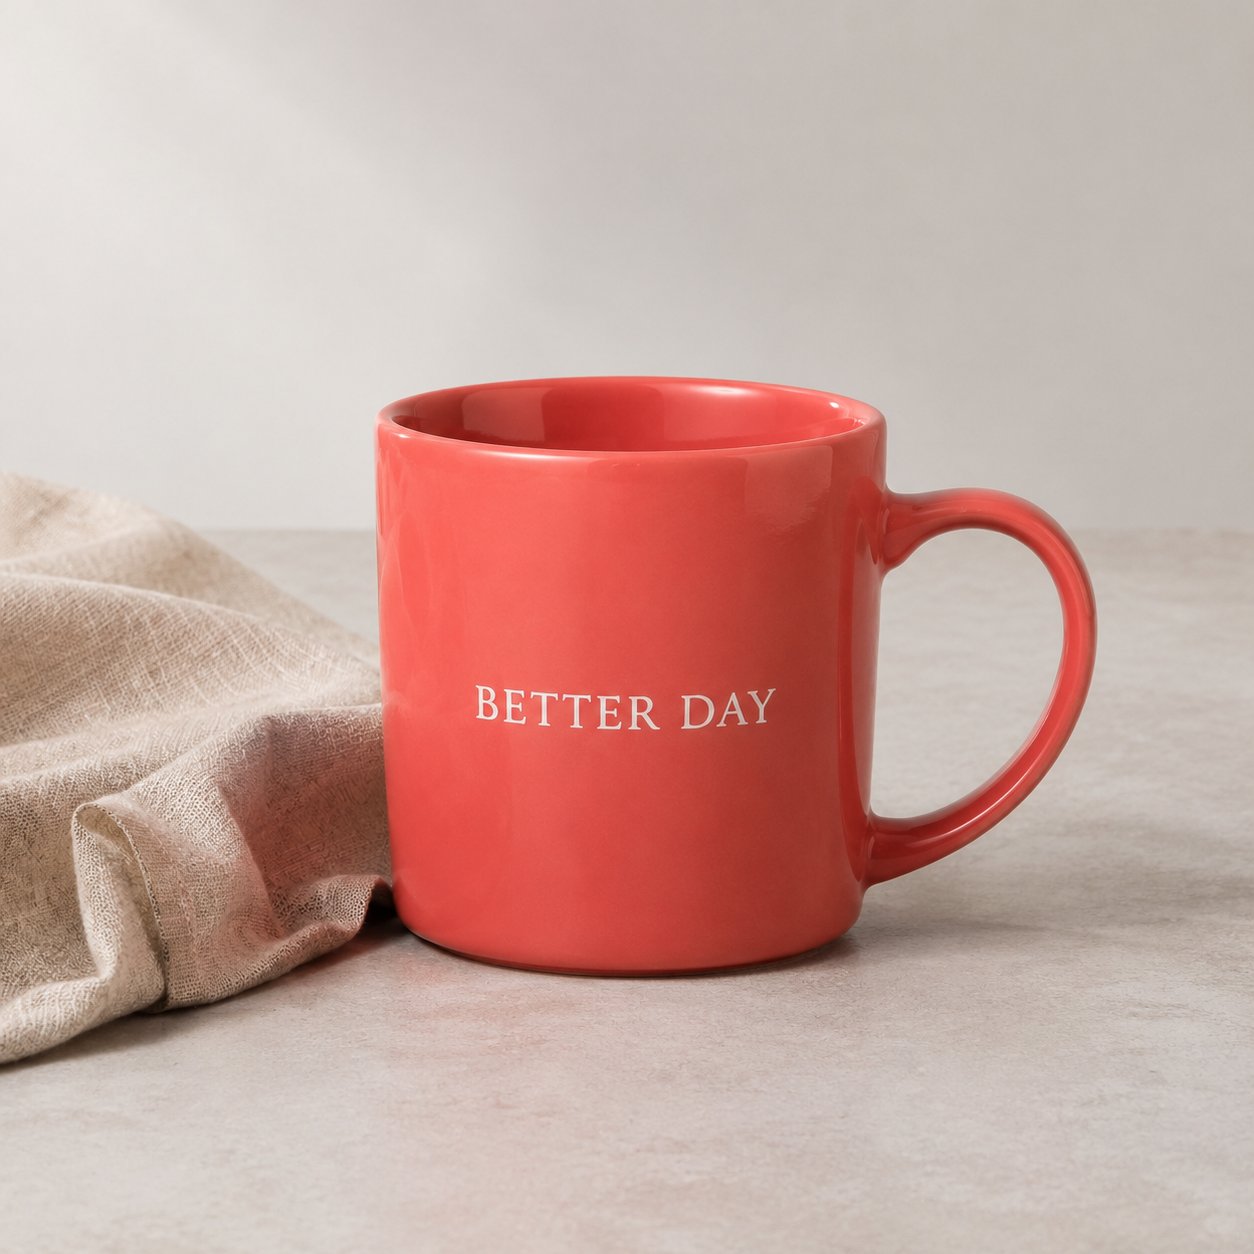
1. Original delivered image for the
1024x1024 request (actual result: 1254×1254):
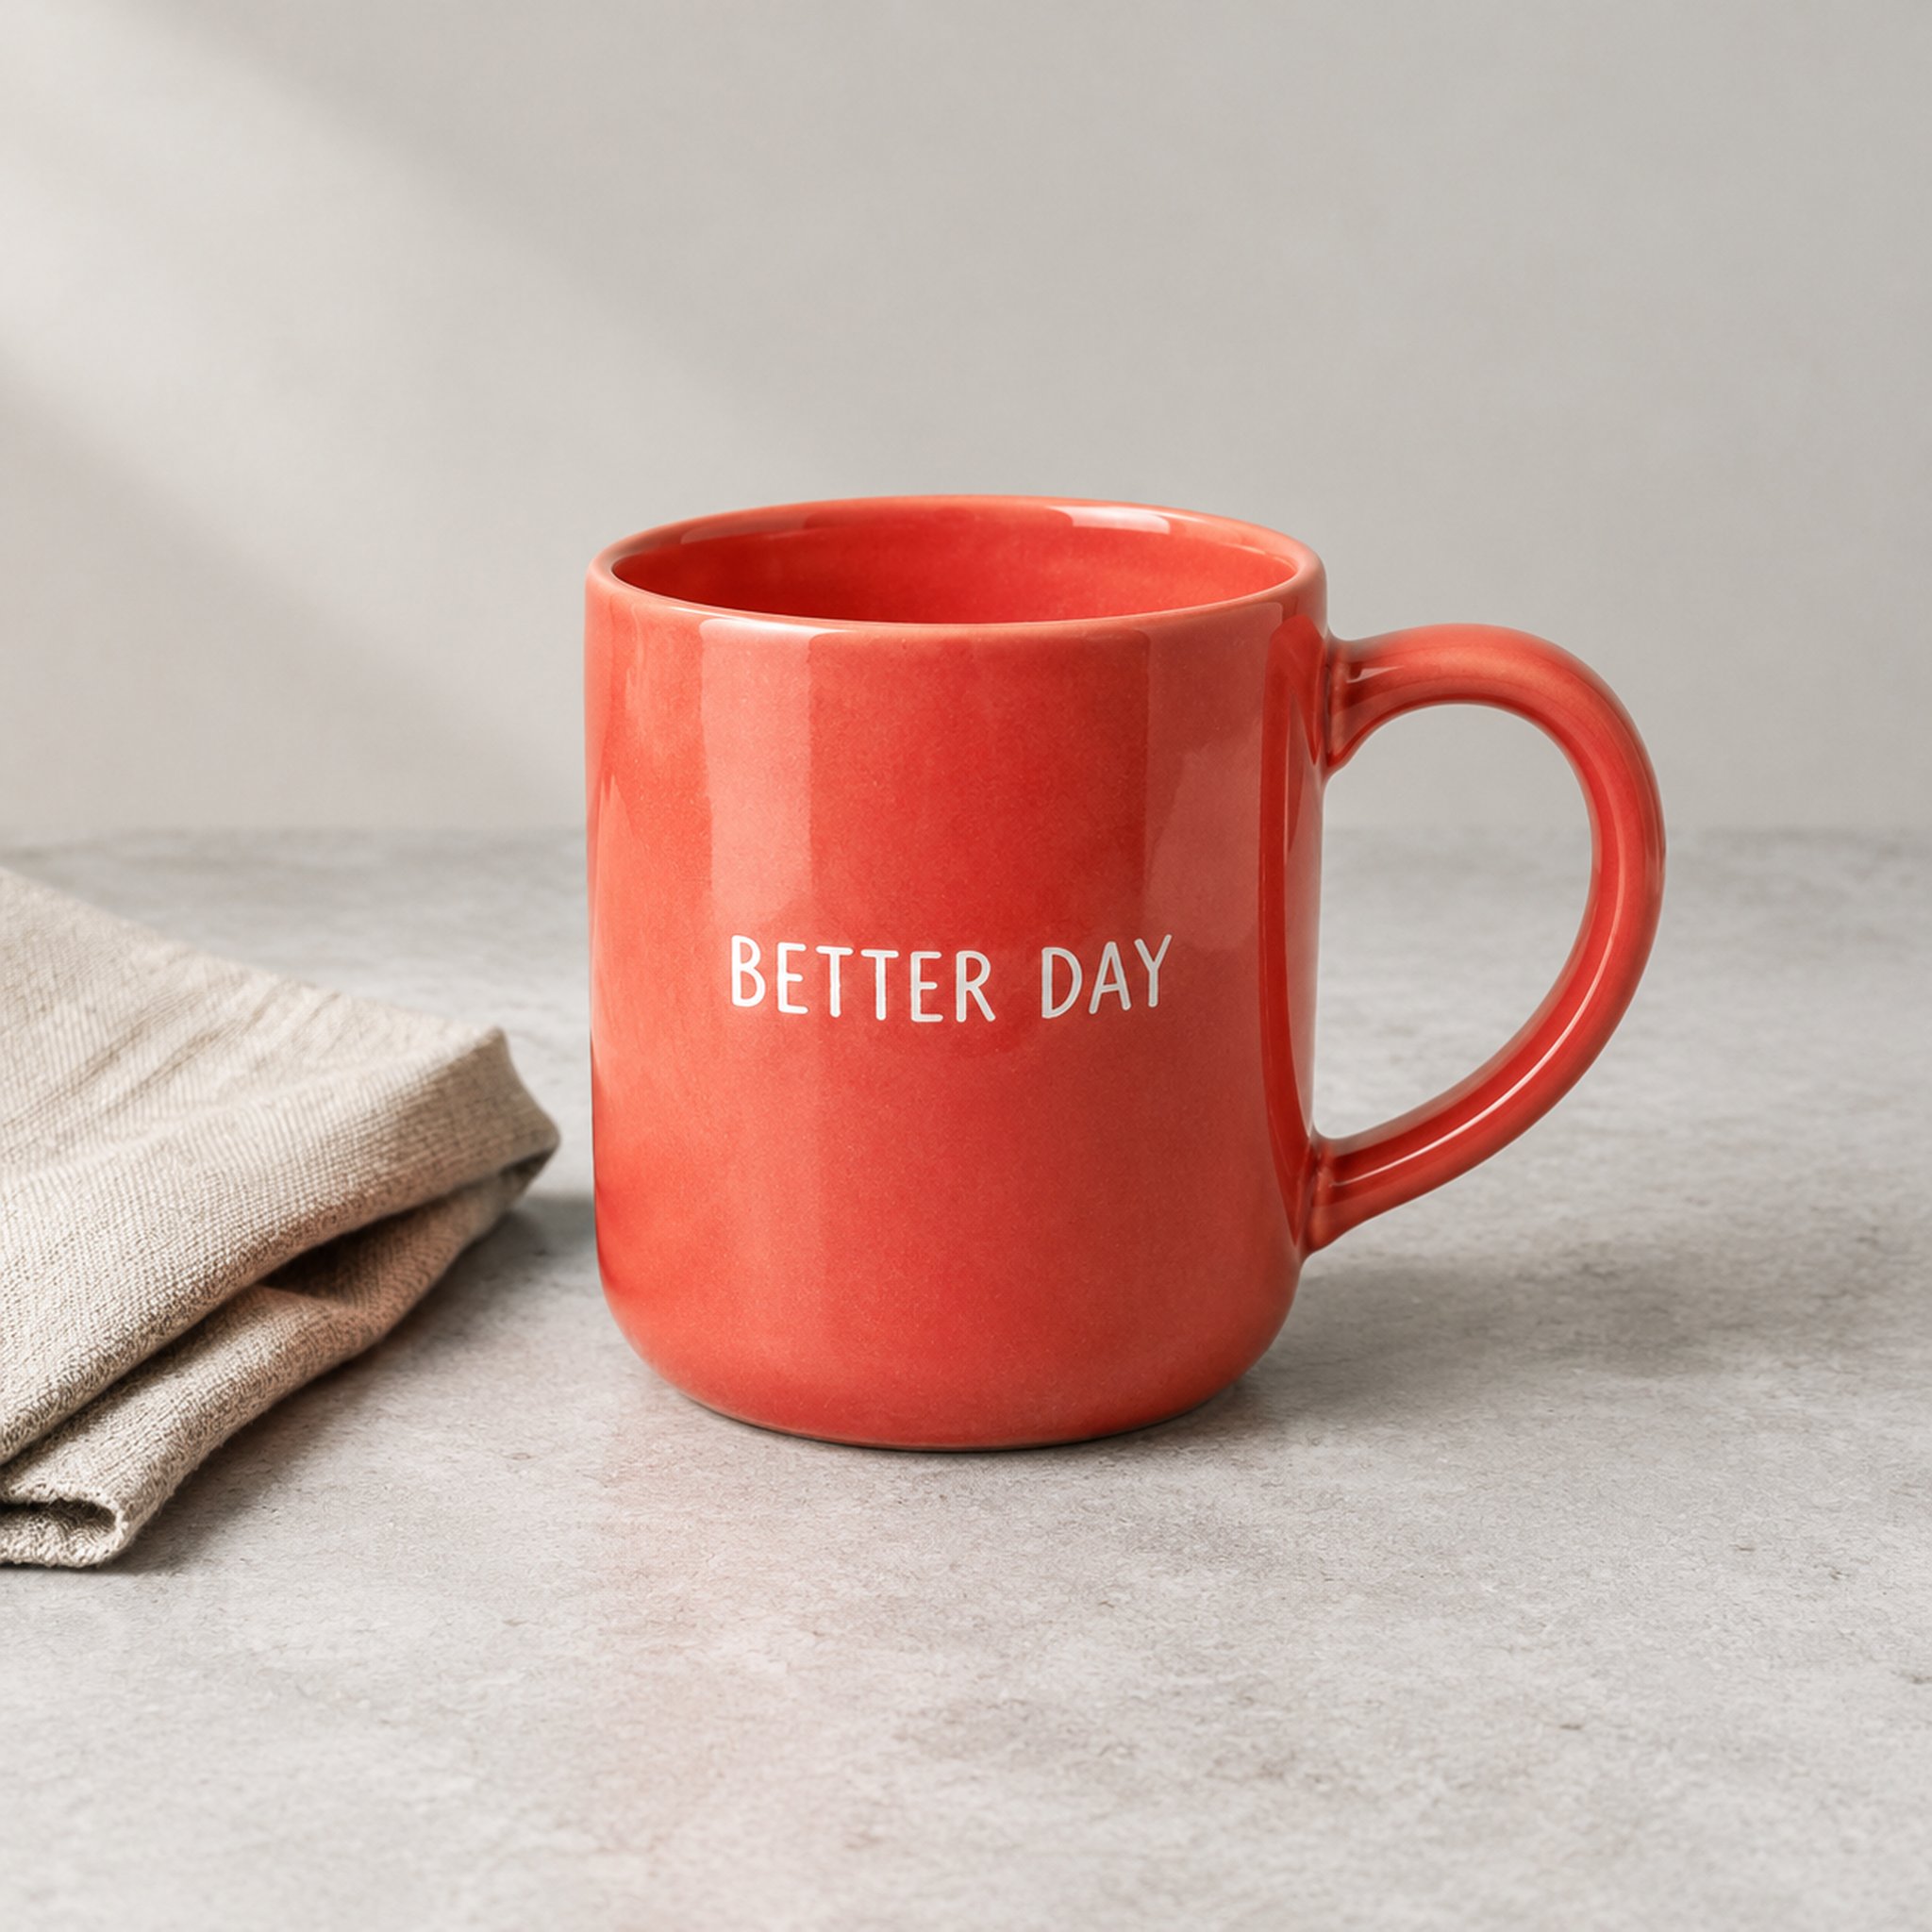
2048x2048 request (actual result: 2048×2048):
3840x2160 request (actual result: 3840×2161):
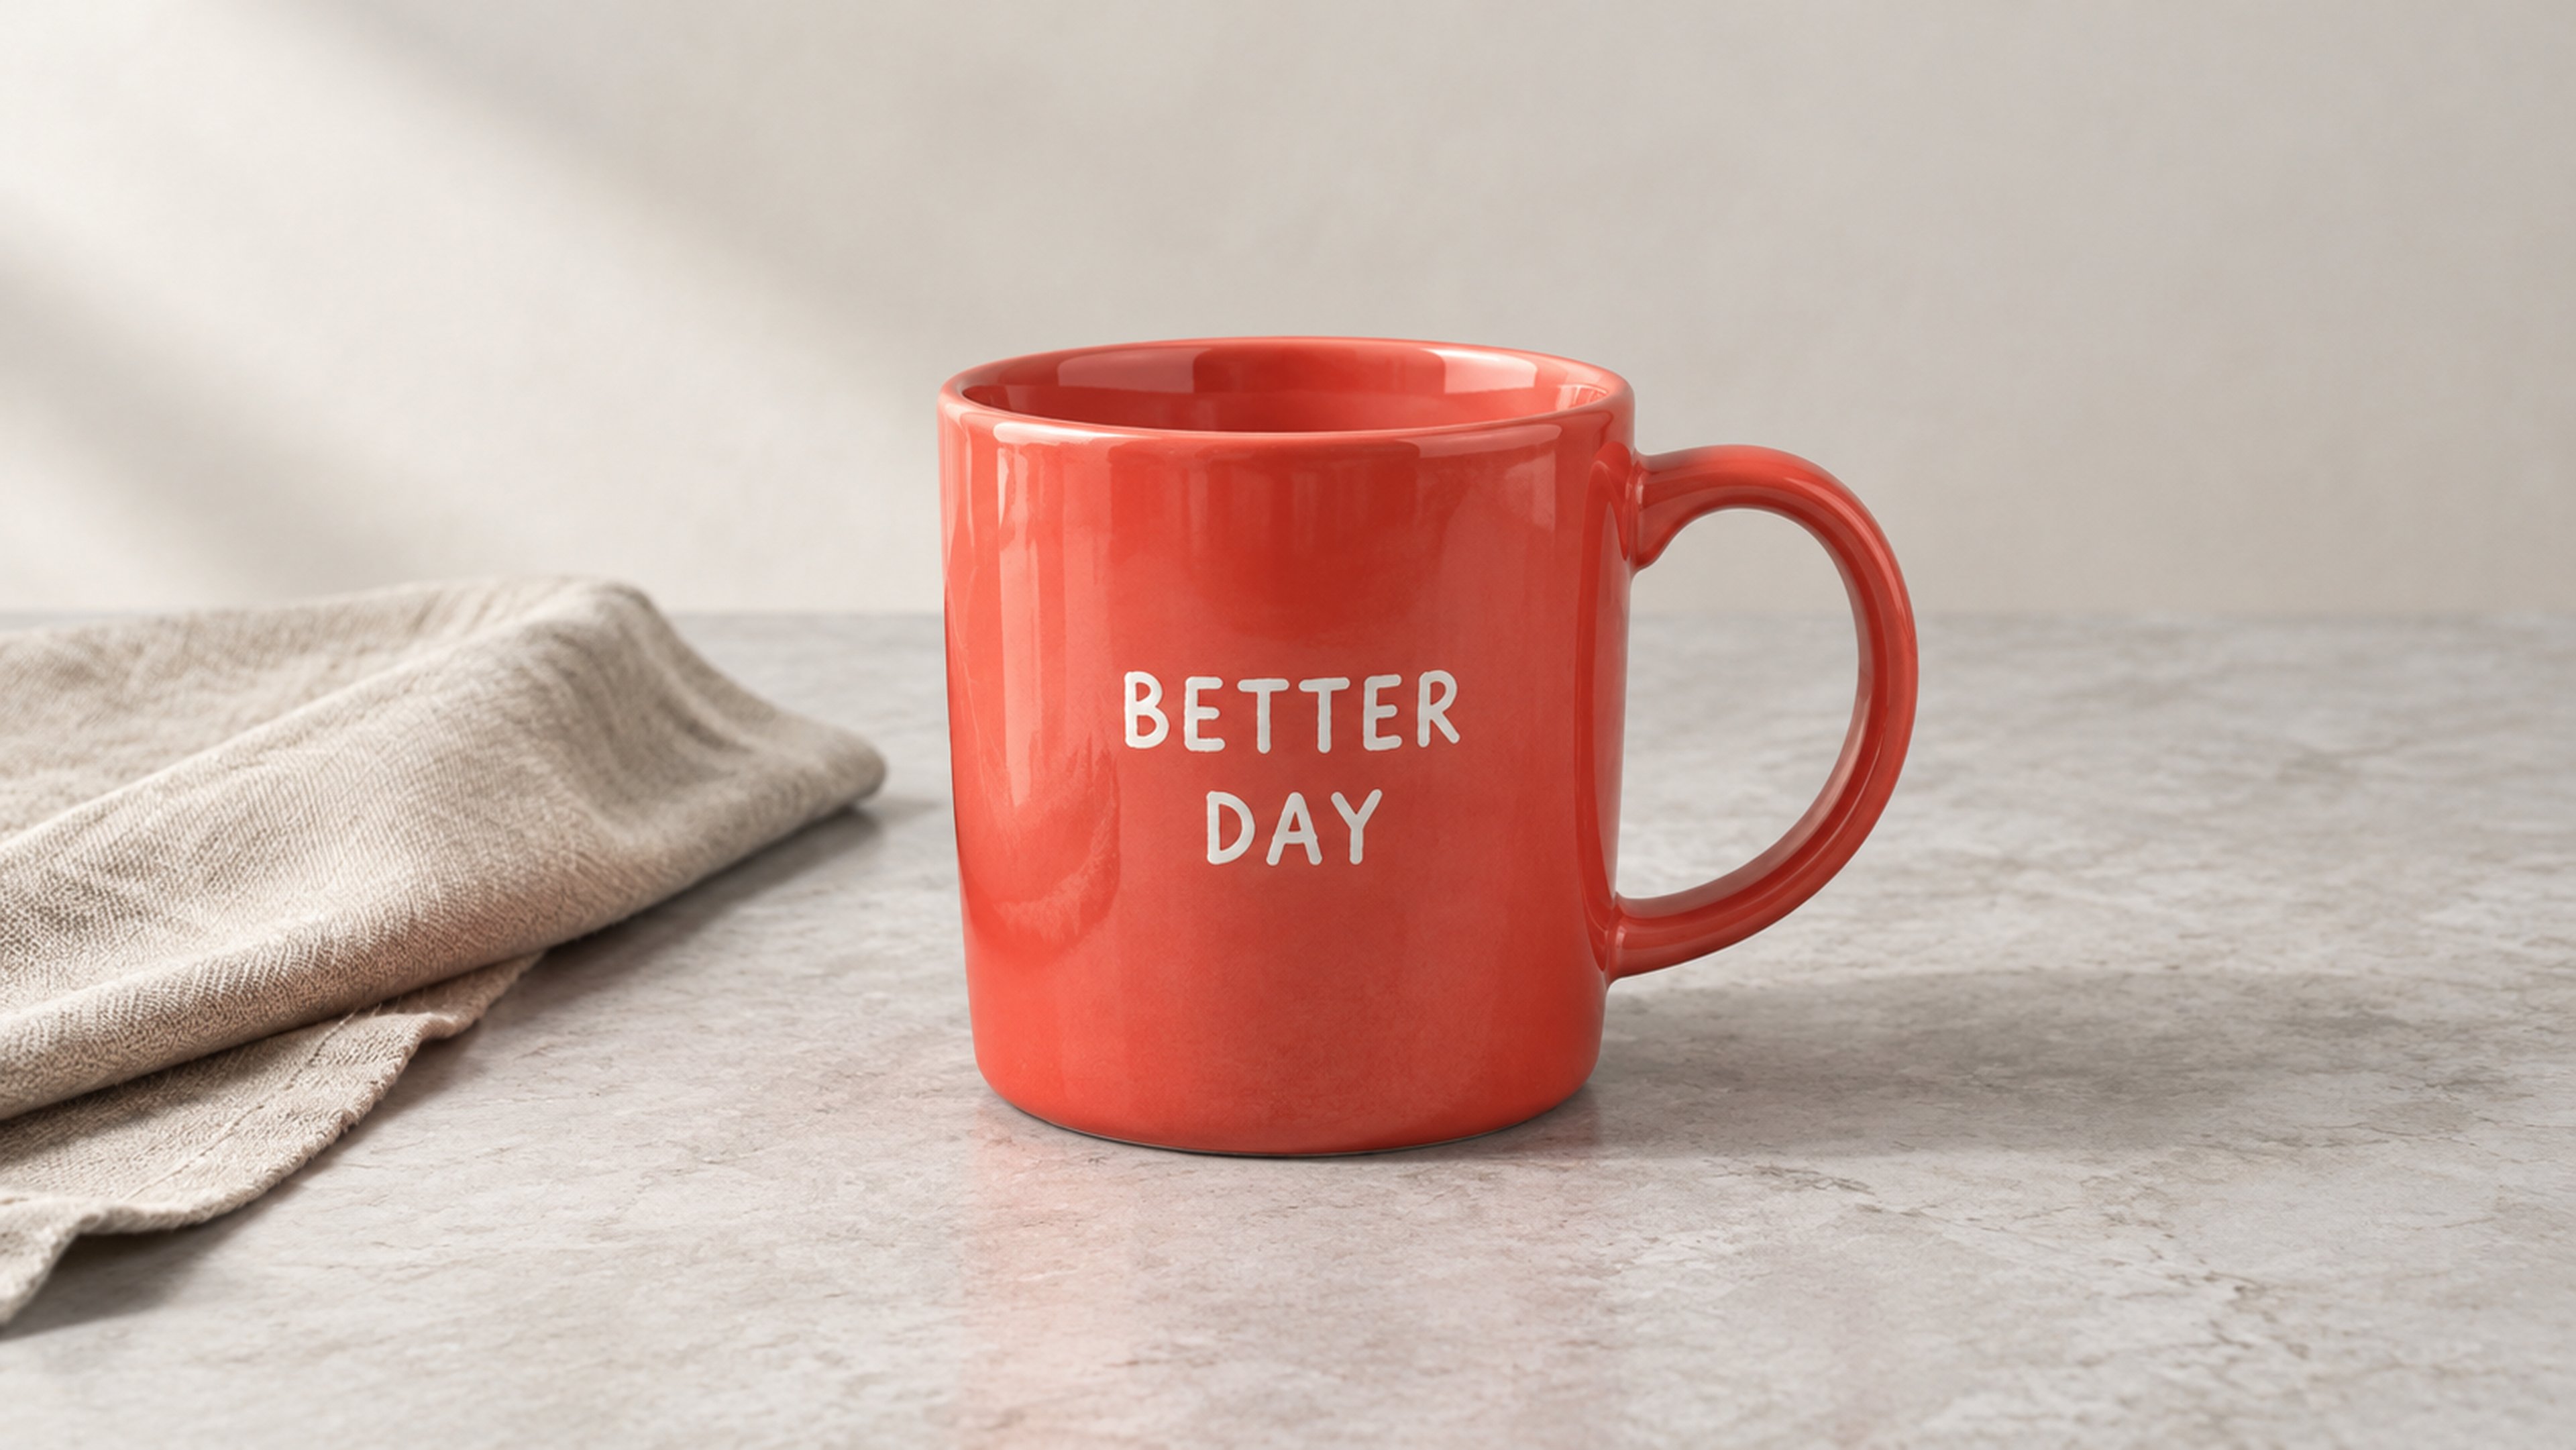
- High visual completeness: All three images show the coral-red glaze reflections, right-side handle, pale gray stone tabletop, beige linen fibers, and clearly readable white “BETTER DAY” lettering.
- Differences from independent sampling: Each generation is an independent sample, so the mug’s proportions, font weight, and cloth folds naturally differ (for example, the lettering in the 4K landscape image is arranged on two lines). The cropped images show the actual details in each image; they are not a controlled optical sharpness test with identical compositions.
- Billing boundary shown directly: Although the first request was for
1024x1024, it delivered a high-resolution1254×1254square image, so it was billed at the same 2K tier (¥0.11) as the second2048×2048image.
Example B: Local product recoloring, showing the actual effect and limits of Mask
We used the first product image from Example A (1254×1254) as the input image and created a same-size Alpha-channel mask image mask-mug.png—only the polygonal mug-body area is transparent (allowed to be redrawn); the handle, inner rim, and background are opaque (must be preserved). The mug lettering is inside the transparent area, and the prompt asks to preserve it.
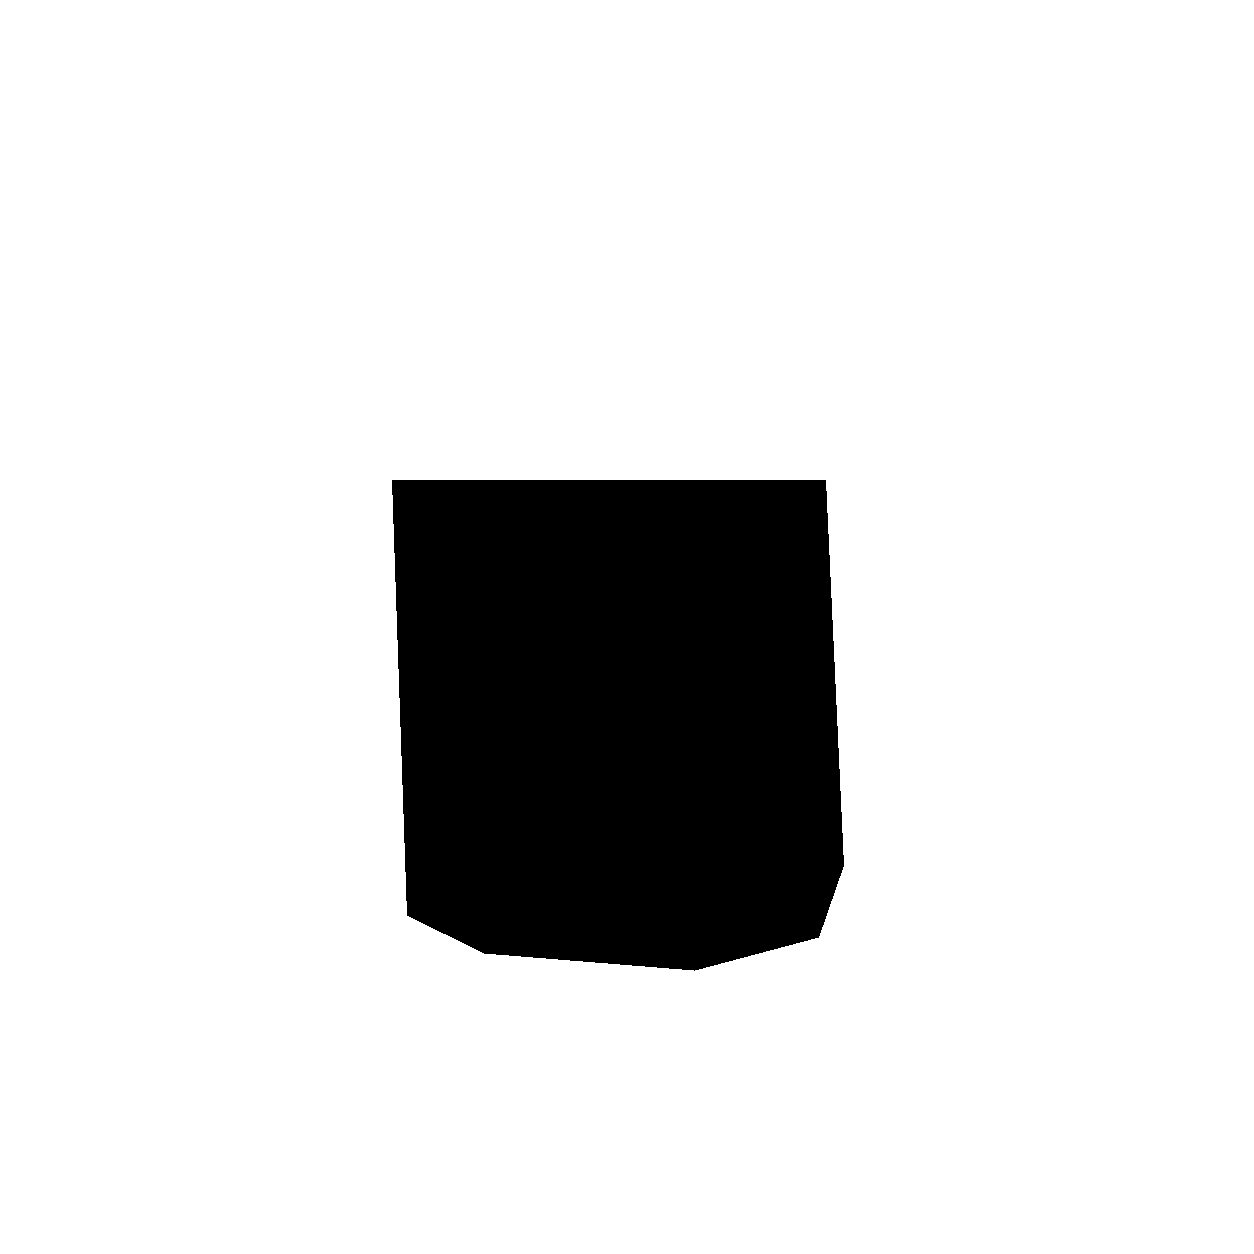
mask-mug.png with an alpha channel.)
Scene design (Chinese concept):
Change only the coral-red mug body inside the transparent mask to deep navy blue. Preserve the ceramic material, lighting, and reflections. Keep the white “BETTER DAY” lettering, red handle, linen cloth, tabletop, background, and overall composition unchanged. Do not add or remove any objects.Actual English prompt used (model:
gpt-image-2, size="2048x2048", quality="high"):
2048×2048, 38.51 seconds, cost ¥0.11):
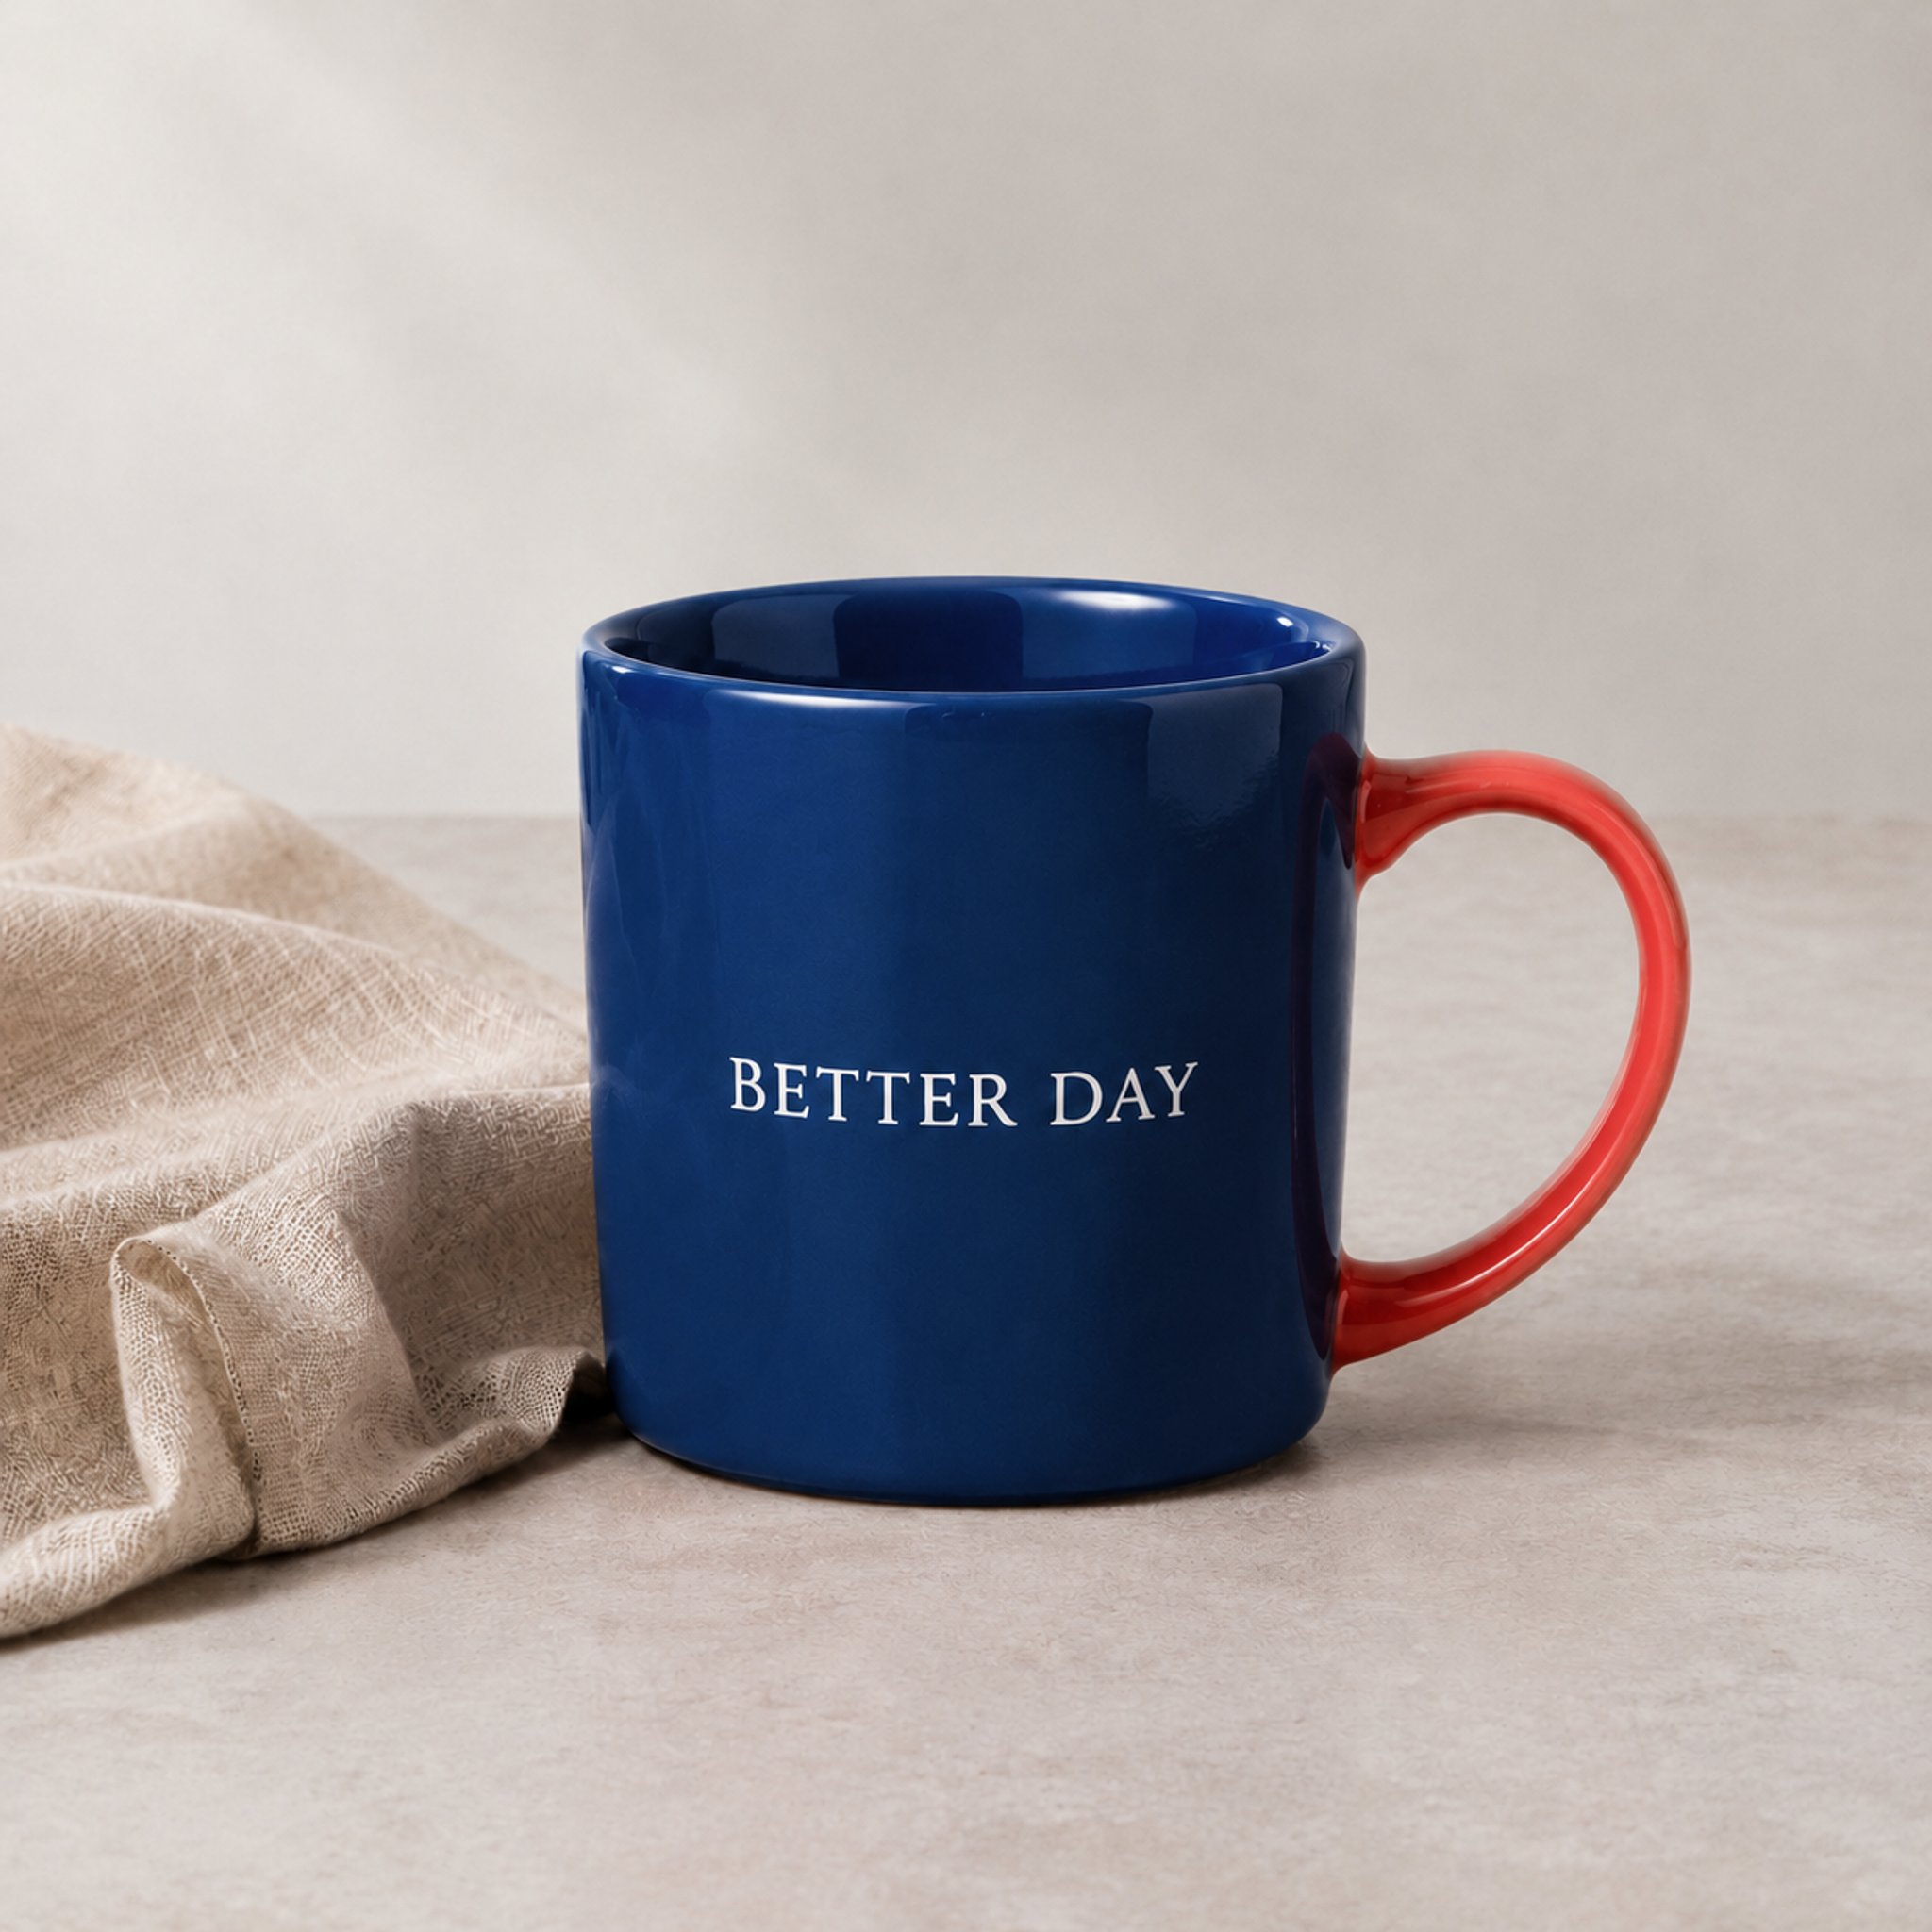
- The main recoloring request was achieved: The outside of the mug body successfully turned deep navy blue while retaining ceramic highlights. The red handle outside the mask, the linen on the left, and the background were generally preserved; the “BETTER DAY” lettering inside the mask remained readable.
- Strict Mask boundary failed (changes spread beyond the mask): A close look at the rim and inner wall shows that the coral-red areas originally inside the opaque protected region were also changed to deep blue. In the more extreme geometric “two circles changed color” test, the unmasked right-hand circle also changed color.
- Usage recommendation: When uploading a reference image and Mask, make sure their canvas dimensions match (transparent where changes are allowed, opaque where content must be preserved), and state both “what to change” and “what to preserve” in the prompt. For industrial or commercial images with brand logos, small packaging text, or strict edge requirements, always zoom in and inspect protected-area boundaries after generation.
7. Prices and actual usage costs: what are you ultimately charged?
BetterToken is committed to transparent pricing. The following is a public price snapshot for 2026-10-19 (CNY applies to enterprise RMB accounts; USD applies to regular USD accounts. These are priced independently and are not converted using live exchange rates):
At the public unit prices above, assuming all 100 generated images are actually delivered in the corresponding billing tier, the reference cost for 100 calls is as follows (arithmetic estimate):
💡 Key budgeting point: estimate costs by the “actual delivered tier,” not the “request parameter”! As shown in the tests above, some requests sent today toflare,sunburst, orgpt-image-2for1024x1024(1K) delivered1254×1254images. The system therefore assigned the actual result to 2K (charging ¥0.15 or ¥0.11, rather than the 1K price of ¥0.035). If all 1001024x1024requests toflarereturned1254×1254, those 100 images would cost ¥15.00 (arithmetic estimate) at current prices. The system also assigns tiers using the target dimensions and a reasonable deviation threshold (for example,3840×2159is normally assigned to 4K and1536×1024to 1K). Do not hard-code a recalculation in your business logic based only on whether “the longest side is greater than 1024.” Always use thebettertoken_image_billingfield in the response body as the billing source of truth.
Why can’t you look only at the “low price per image” on the surface?
When comparing image API costs across platforms, developers should account for three costs:- A quote is comparable only when the actual result meets the target dimensions: A request advertised as “4K supported at a very low price” that actually returns a downgraded 1024 image cannot be used in a production environment that needs high-resolution images, so it is not a valid 4K price for comparison.
- Include failures and rework in the total cost: The invalid-parameter tests in this round were free. If an image was successfully delivered but the result was unsatisfactory, submitting another generation is a new request and should be budgeted separately. The 4 product and Mask case images shown in this guide (3 generated images + 1 edit) were each delivered in a single request. The Mask sample had the out-of-mask recoloring described above. Their prices were ¥0.11, ¥0.11, ¥0.13, and ¥0.11, for a real total cost of only ¥0.46 for all 4 images, matching the bill and account deduction exactly. If unstable routes or incompatible parameters force repeated generation, the actual all-in cost of getting one usable asset can rise even when the quoted price per image is low.
- Reduce hidden engineering adaptation costs: BetterToken’s unified parameter conventions, capability-based intelligent routing, and real-time pixel and billing fields reduce the development work needed to adapt each service and compile size and cost information yourself.
8. Copy-ready request examples
Store your BetterToken API Key in theBETTERTOKEN_API_KEY environment variable, then copy and run the commands below to get started.
Example 1: JSON request to generate a high-resolution product image (POST /v1/images/generations)
The following example calls gpt-image-2 to generate one high-resolution 2048x2048 product image (model can be replaced directly with gpt-image-2.5-flare or gpt-image-2.5-sunburst):
- Size specification: For a 4K landscape image, change
"size"to"3840x2160"(do not use"4096x4096"). Valid dimensions must currently meet all of these conditions: width and height are both multiples of 16, the longest side is no more than 3840, the aspect ratio of long side to short side is no more than 3:1, and the total pixel count is between655,360and8,294,400. - File format identification: Even when the request specifies
"output_format": "png", some underlying nodes may return binary content in JPEG format. When saving or processing images, identify the actual image format from its header (Magic Bytes); do not hard-code the file extension.
Example 2: Multipart reference image and Mask-based local editing (POST /v1/images/edits)
Prepare the original image product-1k-0.png and a same-size transparent mask mask-mug.png (if you only need regular reference-image editing, delete the -F "mask=..." line):
Example 3: Read actual delivered pixels and billing information (response structure and parsing code)
In addition to the standarddata[].b64_json, BetterToken’s response body contains the bettertoken_image_billing extension field:
References: